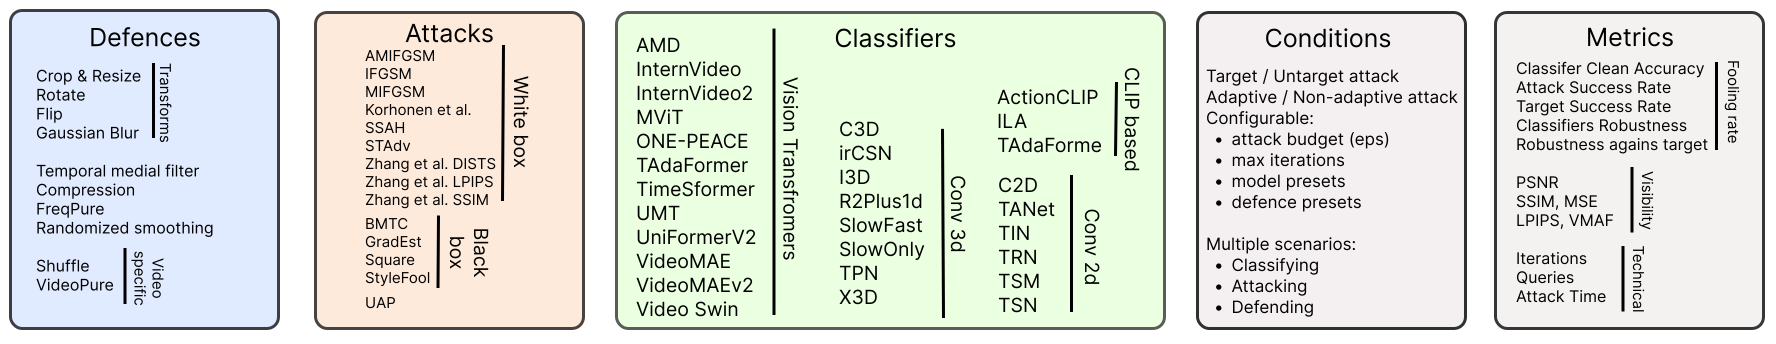
Threat model: full white-box L∞ with ε = 8/255. Dataset: Kinetics-400 validation set. Attacks run in both untargeted and targeted modes. Defences can be applied non-adaptively or adaptively (adversary optimises through the defence).
Robustness of image classification has several benchmarks, but their video counterparts are absent. In video classification the temporal dimension introduces additional degrees of freedom for adversarial attacks, defenses, and preprocessing. Temporal sampling, perturbation budgets, and metric aggregation also interact in ways with no direct analogue in the image setting. Therefore, robustness for video classifiers is studied across scattered, incompatible implementations, making reported numbers hard to reproduce and analyze. We introduce VCR-Bench, a modular open-source benchmark framework that standardizes video loading, wrappers for classifiers, adversarial attacks and defenses, perceptual metrics, configuration presets, and result logging. VCR-Bench currently integrates 30 video classification models, 14 adversarial attacks, and 10 defense wrappers under a common evaluation protocol. We evaluate representative video classifiers, attacks, and defenses on a Kinetics-400 subset, reporting clean accuracy, attack success rate, perceptual quality, runtime, and memory usage. VCR-Bench is released with documented installation, reproducible run presets, component-extension interfaces, and scripts for reproducing the reported results at github.com/msu-video-group/vcr-bench.
Aggregated over full white-box attacks, defences, and completed model runs.
| Loading benchmark data… |
Threat model: full white-box L∞ with ε = 8/255. Dataset: Kinetics-400 validation set. Attacks run in both untargeted and targeted modes. Defences can be applied non-adaptively or adaptively (adversary optimises through the defence).
30+ video recognition models spanning CNN (C3D, I3D, SlowFast…), Transformer (TimeSformer, VideoMAE, VideoSwin, MViTv2…), and Vision-Language families (ActionCLIP, InternVideo, AMD, UMT…).
bibtex will be here